
| Quick answer |
|---|
| The best tools for decreasing AI expenses are Langfuse, which is MIT-licensed and free to self-host, and LiteLLM for routing. But the largest savings come from the providers themselves: Anthropic prices cached input reads at a twentieth of the base rate on its current Opus and Sonnet models, and batch requests at half. |
| How we compare |
|---|
| Tools here are separated from the pricing mechanics they help you exploit, and ranked on what each one meters and what its free tier covers. Provider rates come from Anthropic’s published pricing page, checked 12 September 2026; tool pricing comes from vendor pages, labelled where the vendor publishes no full rate card. No vendor paid for placement. We ran no head-to-head lab test. |
Table of Contents
The biggest savings are in the API, not in a dashboard
Before you buy anything, use the three discounts your provider already offers. Together they beat any tooling decision, and none requires a subscription:
- Prompt caching. Anthropic prices cache reads at 0.05x the base input rate on Opus 5.5 and Sonnet 5.5 — a 95% saving on the cached portion (older models are billed at 0.1x). Writes cost 1.25x on the five-minute TTL and 2x on the one-hour TTL, so break-even is two requests on the short TTL and three on the long. The catch: caching is a prefix match, so one changed byte early in the prompt — a timestamp, an unsorted JSON key — invalidates everything after it.
- Batch processing. Anthropic’s Batch API runs at 50% of standard prices, handling up to 100,000 requests per batch, with most completing inside an hour and a 24-hour ceiling. OpenAI’s equivalent is also widely reported at a 50% discount.
- Model routing. Anthropic’s published API pricing (re-read on 10 October 2026) lists Claude Opus 5.5 at $4 per million input tokens and $20 output, Sonnet 5.5 at $2 and $10, and the older Haiku 4.5 at $1 and $5. Moving classification and extraction from Opus to Haiku 4.5 is a fourfold cut on those calls, with no measurable quality loss on tasks that simple. The older Opus 5 is still sold at $5 and $25, so check which model your code actually calls before running the numbers below.
Stack all three and a classification pipeline can land near an order of magnitude below where it started — a bigger move than any tool on this page. The honest framing: these tools do not reduce your bill, they show you where it is. For every category side by side, see our full AI tools list.
Best tools for decreasing AI expenses compared
| Tool | What it does | Free tier | Paid entry | Metered on |
|---|---|---|---|---|
| Langfuse | Observability and evaluation | Self-host free (MIT); 50k units/mo cloud | $29/mo | Units: traces, observations, scores |
| Helicone | Proxy logging and analytics | 10,000 requests/mo; self-host | Pro $79/mo, Team $799 | Requests |
| LiteLLM | Routing, fallbacks, team budgets | Fully free, open source | Your infrastructure | Nothing |
| Portkey | Gateway with semantic caching | Yes, limited | Tiered | Requests |
| LangSmith | Tracing and evaluation | Yes | $39/seat/mo | Traces |
| Braintrust | Evaluation-first platform | 1 GB data, 10,000 scores | $249/mo | Data volume and scores |
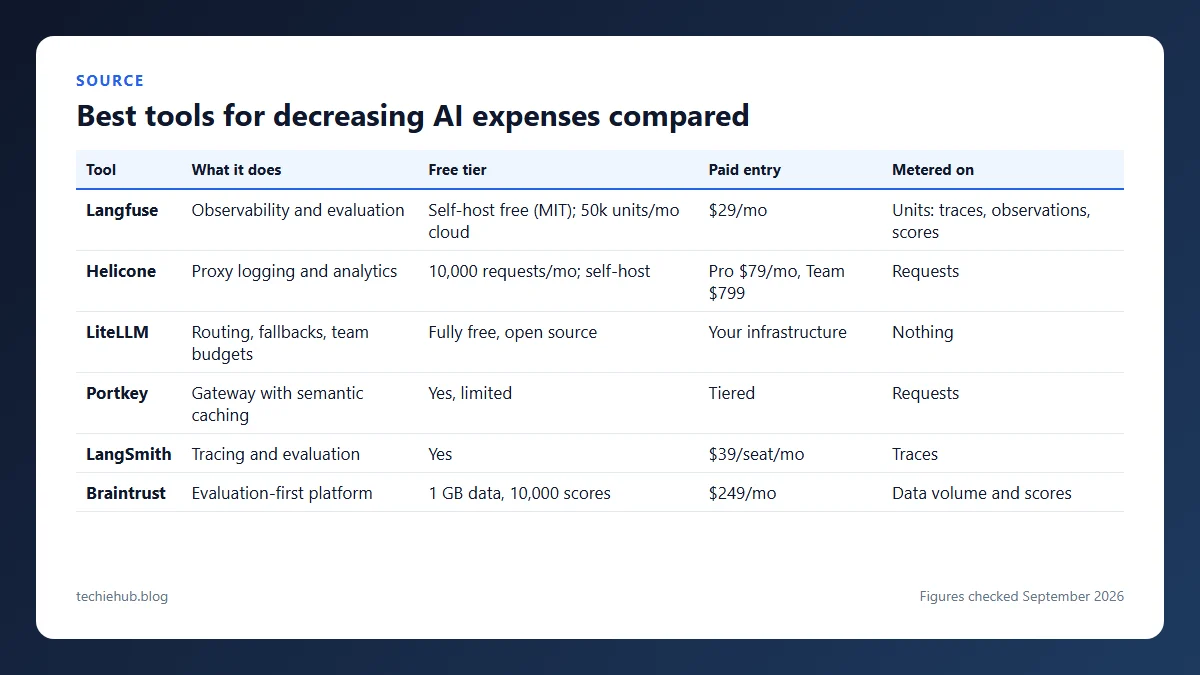
The six tools in detail
Langfuse
Langfuse is the strongest open-source option. Every product feature moved to the MIT licence in June 2025, so self-hosting gives you the full platform with no seat, retention or usage caps. Cloud pricing is metered in units — traces, observations and scores — with a free Hobby tier at 50,000 units a month, Core at $29 and Pro at $199, and overage at $8 per 100,000 units. Usage monitoring overlaps with the AI ops tools we compare separately.
Helicone
Helicone is a proxy that sits in front of your model calls and logs every request — the fastest way to find where the money goes. The cloud tier is free up to 10,000 requests a month with seven days of retention, Pro is $79 a month and Team $799, and self-hosting runs from a single Docker Compose command.
LiteLLM
LiteLLM is free and open source; you pay only for the infrastructure you run it on. As a proxy it gives you one API across providers, per-team budgets and automatic fallbacks, which is what makes model routing practical. For the models underneath these tools, see our comparison of the leading AI models.
Portkey
An AI gateway whose caching is among the most developed in the category, including semantic caching that matches near-identical prompts rather than exact strings. Free tier plus paid plans; Palo Alto Networks completed its $117 million acquisition of Portkey on 29 May 2026, per its annual report, and the gateway now sits inside its Prisma AIRS security platform.
LangSmith
The tracing and evaluation platform most LangChain teams land on. Third-party pricing breakdowns put Plus at $39 per seat per month including 10,000 base traces, with overage at $2.50 per 1,000 base traces on 14-day retention and $5.00 per 1,000 on 400-day retention.
Braintrust
Evaluation-first, with a free Starter tier of 1 GB of processed data, 10,000 scores and unlimited users. Pro is listed at $249 a month including 50,000 scores, with overage at $1.50 per 1,000 scores and $3 per GB of data — so cost tracks evaluation volume, not request volume.
The break-even: what a paid tool has to save to pay for itself
Nobody in this category publishes the number that decides the purchase: how much traffic you need before an observability subscription is cheaper than the waste it finds. It is a two-line calculation — take the saving one mechanism delivers per million input tokens, then divide the subscription price by it.
| Saving mechanism | Published rate change | Saved per 1M input tokens | Volume to cover Braintrust Pro ($249/mo) | Volume to cover LangSmith Plus ($39/seat) |
|---|---|---|---|---|
| Cache reads on Claude Opus 5.5 | $4.00 → $0.20 (0.05×) | $3.80 | $249 ÷ $3.80 = 65.5M tokens | $39 ÷ $3.80 = 10.3M tokens |
| Cache reads on Claude Sonnet 5.5 | $2.00 → $0.10 (0.05×) | $1.90 | $249 ÷ $1.90 = 131.1M tokens | $39 ÷ $1.90 = 20.5M tokens |
| Batch API on Claude Opus 5.5 input | $4.00 → $2.00 (50%) | $2.00 | $249 ÷ $2.00 = 124.5M tokens | $39 ÷ $2.00 = 19.5M tokens |
| Routing Opus 5.5 work to Haiku 4.5 | $4.00 → $1.00 | $3.00 | $249 ÷ $3.00 = 83.0M tokens | $39 ÷ $3.00 = 13.0M tokens |
Read the last two columns as a threshold. If you are not moving tens of millions of input tokens a month, the subscription is the larger cost, not the saving. A $39 seat pays for itself at roughly 10.3 million cached Opus 5.5 input tokens; a $249 platform needs about 66 million — real numbers for a production system, absurd ones for a prototype.
The same arithmetic exposes how these tools price themselves. LangSmith Plus bundles 10,000 traces into $39, or $3.90 per thousand, against a published overage of $2.50 per thousand. Braintrust Pro bundles 50,000 scores into $249, or $4.98 per thousand, against $1.50 marginal. The units inside the subscription cost 1.6 and 3.3 times the units outside it — these plans are priced against their smallest customer, not their largest.
The order to do this in
Sequence matters more than tool choice — each step tells you whether the next is worth doing:
- Measure first, for free. Self-hosted Langfuse or Helicone’s free tier will tell you within a day which routes carry the spend. Both emit OpenTelemetry traces, so the instrumentation you write is not locked to either vendor.
- Turn on caching and check that it works. Verify the cache-read token count in the API response. If it is zero across repeated calls, something in the prefix is changing — that is a code bug, not a pricing problem.
- Move everything asynchronous to batch. Half price for a delay most back-office workloads never notice.
- Route by task, not by habit. Reserve the top model for reasoning; send extraction and classification down a tier.
- Only then consider a paid platform. If your monthly model spend is under a few hundred dollars, a $249 subscription is the largest line item you just created.
AI cost optimization is mostly an engineering discipline, not a purchasing decision. If you are choosing providers rather than tuning one, our comparison of the cheapest AI API covers per-token rates across vendors, and the best AI APIs covers the wider field.
Frequently Asked Questions
What are the best tools for decreasing AI expenses?
Langfuse for observability, because it is MIT-licensed and free to self-host, and LiteLLM for routing, because it is free and makes model switching practical. Add Helicone for request-level logging in an afternoon. But the largest single saving is not a tool: Anthropic prices cached input reads at a twentieth of the base rate on its current Opus and Sonnet models and its Batch API at 50%.
What does evaluation tooling cost at production volume for teams cutting AI spend?
More than the sticker price suggests, because these platforms meter different units. LangSmith bills per trace, which works out at roughly $250 a month for 100,000 traces on top of seat cost. Braintrust bills data and scores instead, so a heavy evaluation cadence costs more than heavy traffic. Langfuse meters units at $8 per 100,000. Work out which unit your workload generates most of first.
Do you need a dedicated eval tool for teams cutting AI spend if you already log traces?
Not immediately. Traces tell you what happened; evaluations tell you whether it was any good, and for many teams a spreadsheet of 50 graded examples is enough for months. A dedicated tool pays for itself when you need regression testing — proving a prompt change did not break a case that used to work. Below that, tracing plus a scripted checker covers it, and Langfuse includes evaluation in its MIT release anyway.
How do you evaluate LLM output without ground-truth labels for teams cutting AI spend?
Three approaches, in increasing order of effort. Assertions: check structural facts the output must satisfy — valid JSON, required fields, no forbidden strings. Pairwise comparison: show a judge two outputs and ask which is better, far more reliable than an absolute score. Model-as-judge with a rubric: cheap and scalable, but calibrate it against a few dozen human-graded examples first, or you are measuring the judge rather than the system.
How much do AI cost reduction tools cost?
Every tool here has a free path: Langfuse self-hosted under MIT or 50,000 cloud units a month, Helicone to 10,000 requests, LiteLLM entirely, Braintrust to 1 GB of data and 10,000 scores, Portkey on a limited tier. Paid entry runs $29 for Langfuse Core, $39 per seat for LangSmith Plus and $249 for Braintrust Pro. Tool cost is almost always a rounding error next to model spend.
One route this list does not cover is removing the API bill rather than trimming it. For steady, low-complexity workloads, running models offline and the differences between Ollama and LM Studio are worth pricing against current spend; our roundup of AI tools for business covers what sits above the model layer.
How much can prompt caching save?
Up to 95% on the cached part of the prompt. Anthropic bills cache reads at 5% of the base input rate on Opus 5.5 and Sonnet 5.5, so Claude Opus 5.5 input drops from $4 to $0.20 per million tokens once the prefix is cached; older models are billed at 10%. Writes cost more, so caching pays back from the second call on the five-minute cache and the third on the one-hour cache.
Conclusion
Start with self-hosted Langfuse or Helicone’s free tier to find where the spend sits, add LiteLLM when routing becomes worth automating, and only pay for LangSmith or Braintrust once regression testing is a real requirement.
Then spend the effort where the money is: caching at a twentieth of base input cost on current models, batching at half price, and routing simple work down a tier beat any observability subscription you can buy. If inference volume is the real problem, running smaller models yourself is the next lever — our guides to the best local LLMs and open source LLMs cover that route.
